RPU -- A Reasoning Processing Unit
By Matthew Joseph Adiletta, Gu-Yeon Wei and David Brooks
Harvard University
Abstract
Large language model (LLM) inference performance is increasingly bottlenecked by the memory wall. While GPUs continue to scale raw compute throughput, they struggle to deliver scalable performance for memory bandwidth bound workloads. This challenge is amplified by emerging reasoning LLM applications, where long output sequences, low arithmetic intensity, and tight latency constraints demand significantly higher memory bandwidth. As a result, system utilization drops and energy per inference rises, highlighting the need for an optimized system architecture for scalable memory bandwidth.
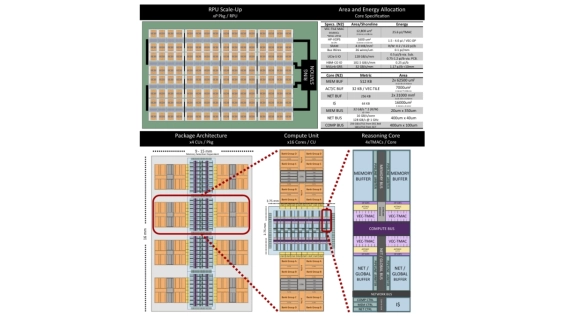
To address these challenges we present the Reasoning Processing Unit (RPU), a chiplet-based architecture designed to address the challenges of the modern memory wall. RPU introduces: (1) A Capacity-Optimized High-Bandwidth Memory (HBM-CO) that trades capacity for lower energy and cost; (2) a scalable chiplet architecture featuring a bandwidth-first power and area provisioning design; and (3) a decoupled microarchitecture that separates memory, compute, and communication pipelines to sustain high bandwidth utilization. Simulation results show that RPU performs up to 45.3x lower latency and 18.6x higher throughput over an H100 system at ISO-TDP on Llama3-405B.
To read the full article, click here
Related Chiplet
- FlexGen Multi-Die Smart Network-on-Chip (NoC) IP
- Ncore Multi-Die Interconnect IP
- Integrated voltage regulator (IVR) chiplet
- High-performance connectivity chiplets
- eFPGA Chiplet
Related Technical Papers
- Performance Implications of Multi-Chiplet Neural Processing Units on Autonomous Driving Perception
- Effects of Poor Workload Partitioning on System Performance for Chiplet-Based Systems
- Link Quality Aware Pathfinding for Chiplet Interconnects
- LEXI: Lossless Exponent Coding for Efficient Inter-Chiplet Communication in Hybrid LLMs
Latest Technical Papers
- Divide and conquer: Scalable performance and energy in MCM GPUs
- A Composable AI-Accelerated Iterative Solver for 3D-IC Thermal Modeling
- QBX: A Compiler for 2-local Qubit Hamiltonian Simulation on Quantum Chiplets
- U-Can-Inject-Errors (UCIe): A Protocol-Aware Hardware Trojan for FPGA Chiplet Links
- The Power of Indirection: Scaling Switches Beyond Silicon Boundaries