Location-Aware Caching Mechanism for minimizing performance degradation induced by inefficient inter-chiplet data path
Jingyang Zheng 1, Huajin Sun 2, Yuning Zhan 1, Chao Fu 1,3, Zhiyuan Zhang 1, Jun Han 1
1 State Key Laboratory of Integrated Chips and Systems, Fudan University, Shanghai, 200433, China
2 Shandong Bosuan Zhixin Information Technology Co., Ltd, Jinan, 250101, China
3 Shao-Chips Laboratory, Fudan University, Shaoxing, 312000, China
Abstract
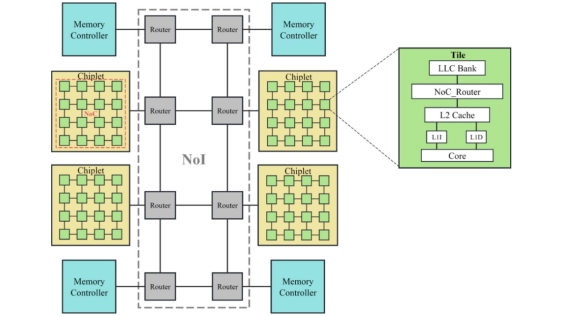
Chiplet-based multicore CPU systems are increasingly recognized as a promising approach for performance scalability. However, this emerging paradigm poses new challenges for the last-level cache (LLC) organization. The high latency and limited bandwidth of the interposer, which connects multiple chiplets, significantly exacerbate inter-chiplet communication delays. Despite the growing importance of chiplet-based systems, research on optimizing LLC organization for these architectures remains limited. Existing strategies, originally developed for monolithic systems or multi-chip module GPUs, fall short in efficiently reducing data access latency.
This paper presents a Location-Aware Caching Mechanism (LACM) for the LLC, specifically designed for chiplet-based multicore systems. LACM replicates data across chiplets and enables the sharing of replicas within each chiplet, thereby reducing costly inter-chiplet communication. Furthermore, LACM incorporates a hardware predictor that enables LLC banks holding replicas to adaptively bypass remote home banks. This selective direct memory access mechanism optimizes both data access latency and cache utilization. We evaluate our work on a 4-chiplet, 64-core system, where LACM improves overall performance by 25.3% over the baseline and outperforms the state-of-the-art techniques Locality-Aware Replication, L1.5, and SAC by 20.3%, 8.8%, and 7.0%, respectively.
Keywords: Chiplet architecture, Multicore system, NUCA effect, Cache hierarchy
To read the full article, click here
Related Chiplet
- FlexGen Multi-Die Smart Network-on-Chip (NoC) IP
- Ncore Multi-Die Interconnect IP
- Integrated voltage regulator (IVR) chiplet
- High-performance connectivity chiplets
- eFPGA Chiplet
Related Technical Papers
- Effects of Poor Workload Partitioning on System Performance for Chiplet-Based Systems
- LEXI: Lossless Exponent Coding for Efficient Inter-Chiplet Communication in Hybrid LLMs
- CLIP-3D: Closed-Loop Evaluation of Performance and Physical Constraints for 3D ICs
- DICE: Detailed Inter-Chiplet End-to-End PHY Modeling for Accurate Chiplet Simulation
Latest Technical Papers
- Location-Aware Caching Mechanism for minimizing performance degradation induced by inefficient inter-chiplet data path
- Predicting Cure Evolution and Thermal Endurance of a Highly Filled Epoxy Underfill for Advanced Packaging
- A Unified Interconnection Network for Chiplet-Based Scaling of the BrainScaleS Neuromorphic System
- Fengshui: Demystifying Chiplet Ecosystem and Bespoke Neural Network Accelerator Codesign
- Hardware Trojan Threats to Multi-Chiplet Photonic Neural Network Accelerators