Compass: Mapping Space Exploration for Multi-Chiplet Accelerators Targeting LLM Inference Serving Workloads
By Boyu Li 𝑎𝑏, Zongwei Zhu 𝑏, Yi Xiong 𝑎𝑏, Qianyue Cao 𝑎𝑏, Jiawei Geng 𝑎𝑏, Xiaonan Zhang 𝑏, Xi Li 𝑏
𝑎 School of Computer Science and Technology, University of Science and Technology of China, China
𝑏 Suzhou Institute for Advanced Research, University of Science and Technology of China, China
Abstract
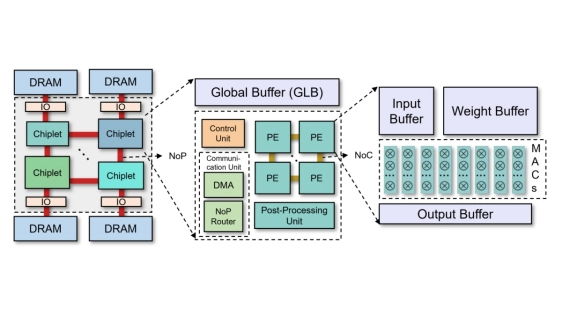
Large Language Models (LLMs) impose massive computational demands, driving the need for scalable multi-chiplet accelerators. However, existing mapping space exploration efforts for such accelerators primarily focus on traditional CNN/Transformer workloads and fail to adequately support the dynamic behaviors of mixed request types and variable sequence lengths in real-world LLM inference serving. To bridge this gap, we first propose a computation execution graph-based mapping encoding scheme that decouples micro-batches and layers, enabling fine-grained execution control on heterogeneous chiplets and flexibly representing various parallelism strategies. Second, building upon this scheme, we develop the Compass framework, which integrates an evaluation engine and a genetic algorithm-based mapping generation engine to achieve efficient mapping search. Compared to state-of-the-art works, our solution achieves an average EDP reduction of 63.12%.
Keywords: LLM inference, chiplet, mapping space exploration.
To read the full article, click here
Related Chiplet
- Optical Chiplet
- Reverse Gearbox Chiplet
- FlexGen Multi-Die Smart Network-on-Chip (NoC) IP
- Ncore Multi-Die Interconnect IP
- Integrated voltage regulator (IVR) chiplet
Related Technical Papers
- Mapping Space Exploration for Multi-Chiplet Accelerators Targeting LLM Inference Serving Workloads
- Beacon: LLM Multi-Agent Driven Hardware Design Space Exploration for Heterogeneous Multi-Chiplet Deep Learning Accelerators
- DeepStack: Scalable and Accurate Design Space Exploration for Distributed 3D-Stacked AI Accelerators
- ThermoDSE: A Thermal-Aware and Comprehensive Design Space Exploration for Chiplet-Based DNN Accelerators
Latest Technical Papers
- Starscream: Reimagining LLM Sharding on AMD Instinct GPUs with GPU Partitioning
- Tri-Stack-PIM: A Heterogeneous Multi-Die 3D-Integrated Processing-in-Memory Architecture for Efficient LLM Inference
- CU-3D: A Scalable Legality-Aware RTL-to-GDS Flow for 3D-IC Physical Design
- Beyond Host-Side Control: HBM Controller Partitioning Across Host and HBM Base Dies
- Chiplet-NAS: Chiplet-aware Neural Architecture Search for Efficient AI Inference on 2.5D Integration