HYDRA: A Heterogeneous Chiplet DSE Framework for Serving Dynamic Hybrid LLM Workloads
By Jiahao Lin 1, Alish Kanani 1, Sangwan Lee 2, Jaehyun Park 2, Umit Ogras 1
1 University of Wisconsin–Madison
2 University of Ulsan
Abstract
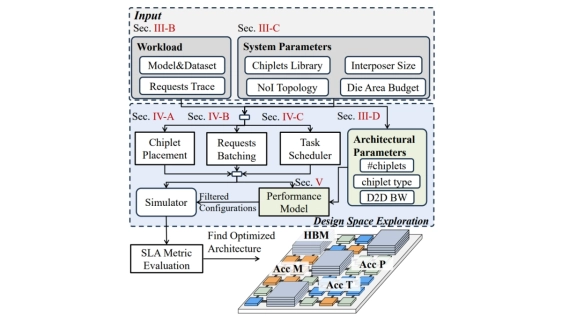
Hybrid Transformer-Mamba large language models (LLMs) enhance long-context efficiency, but their heterogeneous computation and communication patterns complicate efficient hardware acceleration. Chiplet-based architectures offer a scalable solution by integrating specialized compute and memory units. However, the design space spanning static architectural configurations and dynamic runtime policies is prohibitively large to explore exhaustively. To address this challenge, we present HYDRA, a comprehensive design space exploration framework for hybrid LLM serving on heterogeneous chiplet systems. HYDRA jointly explores chiplet composition, placement, inter-chiplet bandwidth provisioning, dynamic batching, and runtime scheduling. It integrates communication-aware placement, dynamic batching, elastic task scheduling, and a fast Markov-based performance estimator that captures multi-tenant runtime dynamics for efficient and accurate exploration. Across all workloads, HYDRA delivers 1.55x the throughput and 43.7 percent lower time-to-first-token on average, with throughput gains reaching up to 2.3x compared to state-of-the-art baselines. These results highlight that co-designing architecture and runtime policies is critical for efficient large-scale LLM serving on heterogeneous chiplet systems.
To read the full article, click here
Related Chiplet
- Optical Chiplet
- Reverse Gearbox Chiplet
- FlexGen Multi-Die Smart Network-on-Chip (NoC) IP
- Ncore Multi-Die Interconnect IP
- Integrated voltage regulator (IVR) chiplet
Related Technical Papers
- Adaptive 3D Chiplet Architecture with Hybrid Wired–Wireless Interconnect for Energy-Efficient Heterogeneous Computing
- A Heterogeneous Chiplet Architecture for Accelerating End-to-End Transformer Models
- Cambricon-LLM: A Chiplet-Based Hybrid Architecture for On-Device Inference of 70B LLM
- AIG-CIM: A Scalable Chiplet Module with Tri-Gear Heterogeneous Compute-in-Memory for Diffusion Acceleration
Latest Technical Papers
- Adaptive 3D Chiplet Architecture with Hybrid Wired–Wireless Interconnect for Energy-Efficient Heterogeneous Computing
- LLM-Augmented Bayesian Optimization with Adaptive Policies for Chiplet Design Space Exploration
- Divide and conquer: Scalable performance and energy in MCM GPUs
- A Composable AI-Accelerated Iterative Solver for 3D-IC Thermal Modeling
- QBX: A Compiler for 2-local Qubit Hamiltonian Simulation on Quantum Chiplets