Making Locality-aware GEMM Compatible with Page-Granularity Placement on Chiplet GPUs
By Euijun Chung, Jae Hyung Ju, Hyesoon Kim
Georgia Institute of Technology
Abstract
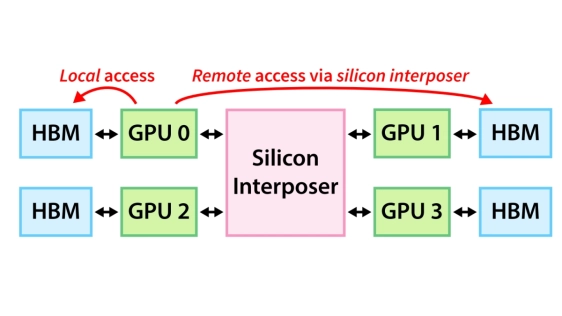
Multi-chiplet GPUs scale compute throughput and high-bandwidth memory (HBM) capacity, but their non-uniform memory system makes locality between chiplets and their data critical to the GPU's performance and energy efficiency. Locality-aware scheduling and data placement identify which data should reside near each chiplet. However, in general matrix multiplication (GEMM), locality-aware data placement often becomes incompatible with a fixed page-granularity data interleaving, since the optimal granularity for mapping data across chiplets varies widely across workloads. We propose Chiplet-Contiguous Layout, a global memory layout that stores chiplet-local data contiguously. Chiplet-Contiguous Layout enables locality-aware placement compatible with page-granularity placement across diverse large language model (LLM) GEMM shapes, without changes to the operating system or hardware. On representative LLM inference and training GEMMs from Qwen 3 30B and Llama 3.1 70B, Chiplet-Contiguous Layout on average reduces remote HBM traffic by 24.7x on Qwen and 19.2x on Llama over 4KB interleaving, and by 4.1x and 2.1x over coarse locality-aware placement.
Index Terms — Chiplet GPU, GEMM, data placement, memory layout, page-granularity placement.
To read the full article, click here
Related Chiplet
- Optical Chiplet
- Reverse Gearbox Chiplet
- FlexGen Multi-Die Smart Network-on-Chip (NoC) IP
- Ncore Multi-Die Interconnect IP
- Integrated voltage regulator (IVR) chiplet
Related Technical Papers
- Starscream: Reimagining LLM Sharding on AMD Instinct GPUs with GPU Partitioning
- On-Package Memory with Universal Chiplet Interconnect Express (UCIe): A Low Power, High Bandwidth, Low Latency and Low Cost Approach
- High-performance, power-efficient three-dimensional system-in-package designs with universal chiplet interconnect express
- Intel Delivers Cutting-Edge Process Technologies to the Data Center with Intel 18A and Advanced Chiplet Packaging
Latest Technical Papers
- Starscream: Reimagining LLM Sharding on AMD Instinct GPUs with GPU Partitioning
- Tri-Stack-PIM: A Heterogeneous Multi-Die 3D-Integrated Processing-in-Memory Architecture for Efficient LLM Inference
- CU-3D: A Scalable Legality-Aware RTL-to-GDS Flow for 3D-IC Physical Design
- Beyond Host-Side Control: HBM Controller Partitioning Across Host and HBM Base Dies
- Chiplet-NAS: Chiplet-aware Neural Architecture Search for Efficient AI Inference on 2.5D Integration