CHIPSMORE: Compute-in-Interconnect and -Memory Chiplets for Multi-Mode Multi-Request LLM Inference Acceleration
By Yue Jiet Chong, Yimin Wang, Zhen Wu, Zixuan Wang, Wei Zhang, Xuanyao Fong
Department of Electrical and Computer Engineering, National University of Singapore, Singapore
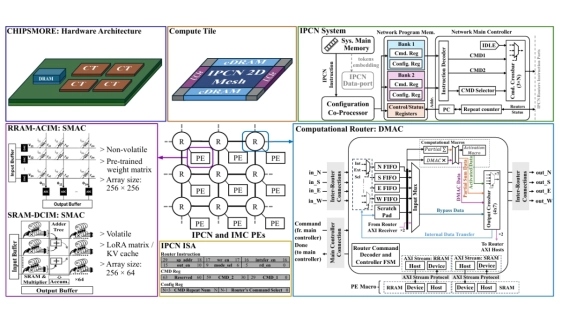
Abstract
Large language model (LLM) inference exhibits substantial variability across adaptation modes, context lengths, and request concurrency, creating challenges for maintaining high utilization, memory efficiency, and scalable performance on compute-in-memory (CIM) accelerators. This paper presents CHIPSMORE, a multi-mode and multi-request LLM inference accelerator that integrates compute-in-interconnect and CIM to support both base-mode and low-rank adaptation (LoRA) inference under diverse workloads. CHIPSMORE employs heterogeneous processing elements consisting of resistive RAM analog compute-in-memory (RRAM-ACIM) and static RAM digital compute-in-memory (SRAM-DCIM) interconnected through a programmable Inter-PE computational network (IPCN). A composable hierarchical key-value (KV) memory scheme dynamically allocates router scratchpad, SRAM-DCIM, and embedded DRAM (eDRAM) resources according to workload requirements, enabling scalable support for long-context and batched inference. Furthermore, a non-replicated multi-request execution pipeline exploits request-level parallelism without duplicating pretrained weights, while a state-aware resource reconfiguration mechanism selectively retains runtime states and power-gates inactive resources to improve energy efficiency. Evaluation using cycle-accurate hardware-software co-simulation demonstrates that CHIPSMORE effectively sustains high throughput across varying model sizes, context lengths, and batch sizes while maintaining favorable power scaling. Compared with Nvidia H100, CHIPSMORE achieves up to 2.38× higher throughput and 27× higher energy efficiency on Mistral-7B inference while eliminating weight replication for multi-request serving.
Index Terms—compute-in-memory (CIM), reconfigurable pre cision, LLM inference acceleration
To read the full article, click here
Related Chiplet
- Integrated voltage regulator (IVR) chiplet
- High-performance connectivity chiplets
- eFPGA Chiplet
- DPIQ Tx PICs
- IMDD Tx PICs
Related Technical Papers
- HALO: Memory-Centric Heterogeneous Accelerator with 2.5D Integration for Low-Batch LLM Inference
- PICNIC: Silicon Photonic Interconnected Chiplets with Computational Network and In-memory Computing for LLM Inference Acceleration
- Mapping Space Exploration for Multi-Chiplet Accelerators Targeting LLM Inference Serving Workloads
- Compass: Mapping Space Exploration for Multi-Chiplet Accelerators Targeting LLM Inference Serving Workloads
Latest Technical Papers
- Predicting Cure Evolution and Thermal Endurance of a Highly Filled Epoxy Underfill for Advanced Packaging
- A Unified Interconnection Network for Chiplet-Based Scaling of the BrainScaleS Neuromorphic System
- Fengshui: Demystifying Chiplet Ecosystem and Bespoke Neural Network Accelerator Codesign
- Hardware Trojan Threats to Multi-Chiplet Photonic Neural Network Accelerators
- Mapping Dynamic, Hierarchical Quantum Circuits