Why UCIe is Key to Connectivity for Next-Gen AI Chiplets
By Letizia Giuliano, VP of IP Products, Alphawave Semi
EETimes (February 6, 2025)
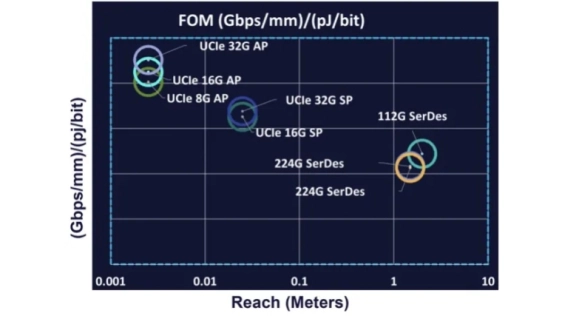
Deploying AI at scale presents enormous challenges, with workloads demanding massive compute power and high-speed communication bandwidth.
Large AI clusters require significant networking infrastructure to handle the data flow between the processors, memory, and storage; without this, the performance of even the most advanced models can be bottlenecked. Data from Meta suggests that approximately 40% of the time that data resides in a data center is wasted, sitting in networking.
In short, connectivity is choking the network, and AI requires dedicated hardware with the maximum possible communication bandwidth.
Deploying AI at scale presents enormous challenges, with workloads demanding massive compute power and high-speed communication bandwidth.
Large AI clusters require significant networking infrastructure to handle the data flow between the processors, memory, and storage; without this, the performance of even the most advanced models can be bottlenecked. Data from Meta suggests that approximately 40% of the time that data resides in a data center is wasted, sitting in networking.
In short, connectivity is choking the network, and AI requires dedicated hardware with the maximum possible communication bandwidth.
The large training workloads of AI create high-bandwidth traffic on the back-end network, and this traffic generally flows in regular patterns and does not require the packet-by-packet handling needed in the front-end network. When things are working properly, they operate with very high levels of activity.
Low latency is critical, as we must have fast access to other resources, and this is enabled by a flat hierarchy. To prevent (expensive) compute being left underutilized, switching also must be non-blocking—it should be noted that the performance of AI networks can be bottlenecked by even one link that has frequent packet losses. Robustness and reliability of the networks are also critical, with the design of the back-end ML network taking this into consideration.
To read the full article, click here
Related Chiplet
- Optical Chiplet
- Reverse Gearbox Chiplet
- FlexGen Multi-Die Smart Network-on-Chip (NoC) IP
- Ncore Multi-Die Interconnect IP
- Integrated voltage regulator (IVR) chiplet
Related News
- EdgeCortix Looks To Chiplets For Third-Gen Reconfigurable AI Chip
- Polaris Electro-Optics Secures $50M Series B to Scale Next-Gen Optical Engine Platform for AI Infrastructure
- CEA-Leti, CEA-List and PSMC Collaborate to Integrate RISC-V and MicroLED Silicon Photonics into 3D Stacking and Interposer for Next-Generation AI
- Amkor Technology Announces Strategic Partnership with NVIDIA to Expand Advanced Packaging and Test for Next-Generation AI Infrastructure
Latest News
- Staera Semiconductor Emerges from Stealth with US$4.6 Million to Build Light into the Chip and Break AI's Data Bottleneck
- Vertical Compute expands partnership with imec to accelerate commercial manufacturing of Vertically Integrated Memory (VIM)
- Imec advances Europe's silicon interposer technology capabilities through NanoIC pilot line, paving the way for open chiplet design
- SCHMID Group Secures Key Wet-Process Equipment Order for South Asia’s First Glass Core Substrate Manufacturing Facility
- EV Group Helps Accelerate Qubit Scaling for Quantum Computing Through Advanced Packaging Expertise