FuriosaAI Partners with Broadcom to Build Next-generation Inference Platform for the Agentic Era
MOUNTAIN VIEW, Calif.-- May 27, 2026 --FuriosaAI, a builder of high-performance inference silicon, today announced a strategic partnership with Broadcom (NASDAQ: AVGO) to develop its third-generation AI accelerator. This collaboration evolves Furiosa’s Tensor Contraction Processor (TCP) architecture into a multi-die chiplet system, creating an inference engine engineered for the high-volume token requirements of global hyperscale environments.
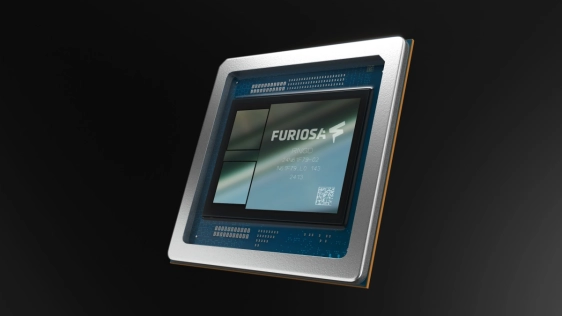 Moving beyond a traditional ASIC partnership, Furiosa and Broadcom are combining Furiosa’s AI architecture with Broadcom’s leadership in AI networking solutions and high-bandwidth Ethernet switches to build a unified inference platform. This collaboration brings together Furiosa’s architectural innovation and Broadcom’s infrastructure expertise to scale AI compute clusters to thousands of nodes.
RNGD: A proven foundation for production inference
The partnership builds on the commercial maturity of RNGD, FuriosaAI’s data center inference chip. Currently in mass production and fabricated at TSMC’s 5nm advanced process, RNGD is a 180W, PCIe-based accelerator designed for high-performance LLM and agentic AI workloads.
RNGD has been validated in production environments by global leaders including Samsung SDS and LG AI Research, proving the efficiency of the TCP architecture in standard, air-cooled data center environments. By providing high throughput and low latency within a power-constrained envelope, RNGD establishes the architectural foundation for the significant enhancements being co-developed with Broadcom for the third-generation platform.
"Inference performance is no longer defined solely by raw compute. It is increasingly a function of data reuse and communication efficiency across servers and racks," said Charlie Kawwas, Ph. D., president of Broadcom’s Semiconductor Solutions Group, "By pairing Furiosa’s TCP architecture with Broadcom’s market-leading XPU Technology and IP Platform, Ethernet scale-up and fabric switches, we are building a platform that addresses the key bottlenecks of large-scale agentic AI."
Scalable chiplet architecture and advanced networking
Furiosa’s third-generation chip will feature a 2nm compute die and HBM4/4E, utilizing Broadcom’s advanced packaging capabilities to integrate multiple silicon dies into a high-performance system-on-chip. By incorporating Broadcom’s Ethernet and PCIe technologies, the system enables high-bandwidth, rack-scale networking across massive AI compute clusters.
“Bringing together Broadcom’s infrastructure capabilities and Furiosa’s Tensor Contraction Processor architecture and its industry-defining software stack allows us to move beyond the chip level and deliver a comprehensive solution for the token factory era,” said Furiosa Cofounder and CEO June Paik. “Having proven the performance and efficiency of our architecture with RNGD, our second-generation chip now in mass production with TSMC, we will deliver a third-generation inference solution that offers industry-leading performance per watt for even the largest, most complex frontier AI models and agentic workloads.”
The design is optimized for demanding real-world AI workloads, including intensive post-training sampling. By focusing on high-bandwidth data movement rather than the thread management required by GPUs, the chip will deliver higher performance-per-watt and greater token density than state-of-the-art GPUs.
Software designed for flexibility and developer velocity
Furiosa’s hardware is supported by a software stack that enables developers to deploy quickly, meet demanding throughput and latency requirements, and easily switch to new frontier models and new optimization techniques.
While legacy platforms require extensive hand-tuning of kernels for every new model, Furiosa’s SDK leverages a general compiler that automatically maps high-level PyTorch code to silicon. For developers requiring more granular control, Furiosa’s Virtual ISA offers a declarative programming model that provides hardware control without the non-deterministic complexity of traditional GPU programming.
Roadmap and availability
Sampling is scheduled to begin in the first half of 2028 to support the next decade of AI data center deployments.
About FuriosaAI
FuriosaAI builds high-performance, high-efficiency AI compute for the Inference Era. Founded in 2017 by veteran engineers from AMD, Qualcomm, and Samsung, Furiosa operates globally with offices in Korea and Silicon Valley. The company has shipped two generations of AI chips based on our proprietary Tensor Contraction Processor (TCP) architecture. Its flagship product, RNGD, runs advanced large language models and agentic AI and is now in mass production. RNGD drops seamlessly into standard, air-cooled data centers to deliver unprecedented "tokens per watt" efficiency, supported by a mature SDK that eliminates the need for vast libraries of hand-tuned kernels. The company has raised $250M through Series C Bridge and works with leading global partners.
For more information, visit furiosa.ai.
Related Chiplet
- Optical Chiplet
- Reverse Gearbox Chiplet
- FlexGen Multi-Die Smart Network-on-Chip (NoC) IP
- Ncore Multi-Die Interconnect IP
- Integrated voltage regulator (IVR) chiplet
Related News
- Cadence Introduces AuraStack AI Super Agent, the World’s First Agentic AI Platform for PCB and Advanced Packaging
- onsemi Introduces the Embedded Power Platform, a Breakthrough Architecture for the AI Era
- JEDEC and Open Compute Project Foundation Pave the Way for a New Era of Chiplet Innovation
- Eliyan Supports Latest Version of UCIe Chiplet Interconnect Standard, Continues to Drive Performance and Bandwidth Capabilities to 40Gbps and Beyond to Help Meet the Needs of the Multi-die Era
Latest News
- Tenstorrent Releases Open Source Beta of the Open Chiplet Atlas® (OCA) Harness
- Building Out Advanced Packaging Portfolio, JCET Delivers Steady Revenue Growth and Improved Profitability in Q3 YTD 2026
- Egis Group and SiPearl Sign Strategic Cooperation and Investment Agreements to Expand Opportunities on a Global Scale
- Unigen Expands AI Module and Server Compute Collaboration to EdgeCortix RAIDEN Platform
- Amkor Technology and NVIDIA Advance Strategic Partnership for AI Infrastructure